What I Did
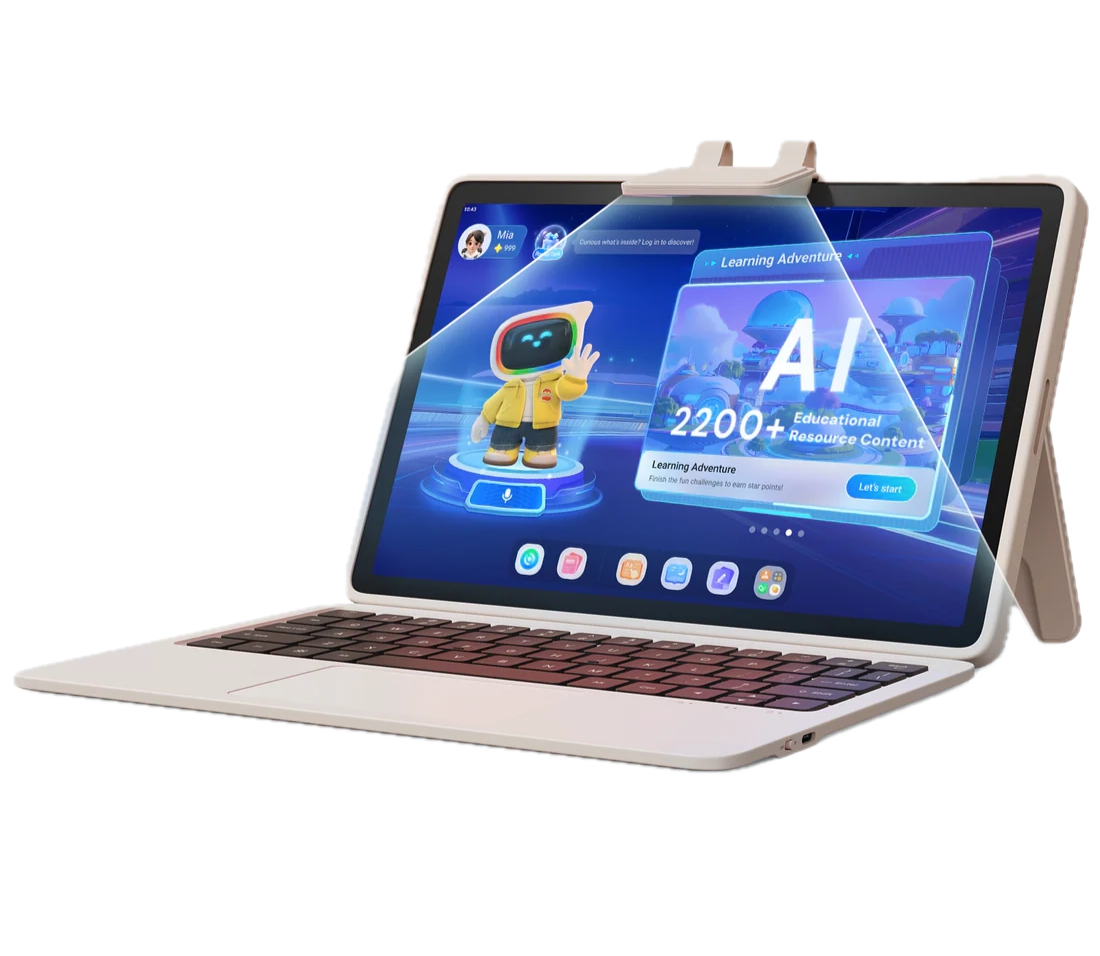
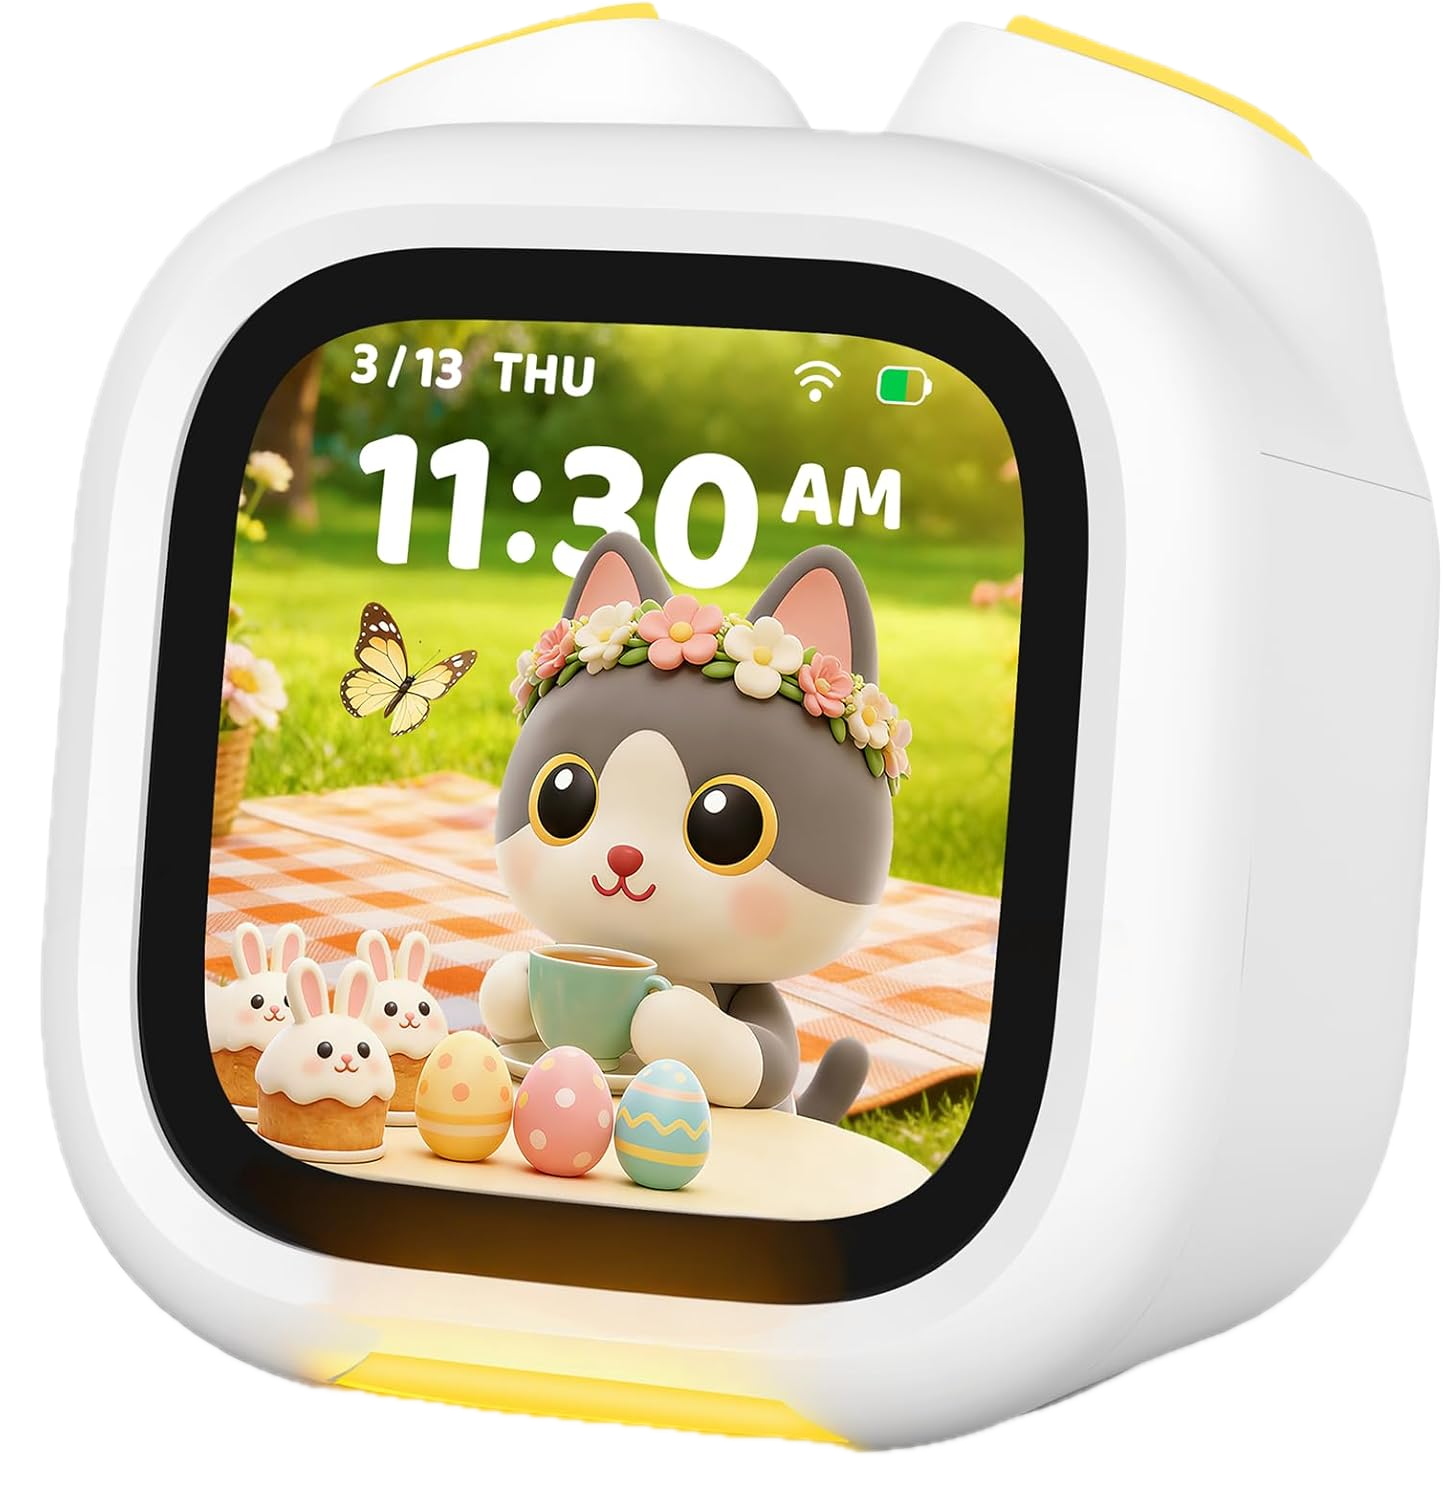
I participated in 10+ structured user interviews across both products, covering assigned topic areas — feature usability, content difficulty calibration, and learning behavior patterns. As a team, we conducted research with 60+ U.S. families through video interviews, daily survey instruments, and direct WhatsApp contact for real-time issue reporting.
I also managed the daily feedback pipeline: consolidating structured submissions into an internal reporting system, categorizing issues by type and frequency, and making prioritization calls on escalation. This meant occasionally overriding the volume-based system — flagging a single user whose device failure made continued testing impossible, even though no one else had reported the same issue.
What I Observed
Reading beyond the numbers: an edge case that mattered
Our triage system usually prioritized issues by volume — the more users reporting the same problem, the higher it ranked. But one report caught my attention precisely because it was unique: a single user whose device had become completely unusable, blocking their ability to continue the test entirely. I reached out directly, collected a video of the issue, and escalated it to the product developer. Resolved within 24 hours. The more important takeaway was about the limits of volume-based prioritization: frequency tells you what's common. It doesn't tell you what's critical.
When the Incentive Loop Breaks Down
The app used a reward mechanic — completing learning activities earned coins and mystery box draws, exchangeable for character customizations. In theory, a straightforward incentive loop. In practice, children couldn't trace the connection between finishing a chapter and receiving a reward. The steps were too indirect, the feedback too delayed. Without a felt connection between effort and outcome, engagement was difficult to sustain.
This pattern emerged across multiple data sources — daily feedback reports flagged recurring disengagement, and parent interviews confirmed the underlying reason: children found the mechanic too complex to follow.
This wasn't a bug — it was a mental model mismatch. The multi-step reward chain placed significant cognitive demand on young learners: to stay motivated, children needed to simultaneously track their learning progress, accumulate currency, and anticipate a deferred reward. For many, this exceeded their working cognitive capacity, making the system feel arbitrary rather than rewarding. From a Self-Determination Theory perspective, the design also undermined the sense of competence that drives intrinsic motivation — when children couldn't feel the direct connection between their effort and a meaningful outcome, the reward loop failed to reinforce the behavior it was designed to encourage.
This is the kind of pattern that surfaces through qualitative research, not only through survey data. It was an early-stage finding that the research team documented and flagged for iteration — part of the ongoing product refinement process that continued across subsequent testing cycles.
What I Learned
Working inside a fast-moving AI product team taught me something that structured research training doesn't fully prepare you for: the gap between what users say and what they actually do is often where the most actionable insights live. Families would rate a feature positively in a weekly survey, then stop using it entirely by day four.
In EdTech AI products specifically, this gap is harder to close than in other product categories. Learning behavior is slow to change, children can't always articulate their experience, and parents act as proxies whose perceptions don't always match what's happening in the actual interaction. Research in this space requires triangulating across data sources rather than relying on any single signal — and staying skeptical of surface-level satisfaction metrics when engagement tells a different story.
That translation work — from observation to recommendation to decision — is something I want to keep developing.